Cloudflare Gives AI Crawlers a Bouncer. The Banner Ad Checks IDs.
Cloudflare’s September 15 bot rules give publishers more control. Mixed crawlers make discovery awkward, and a blocked request still isn’t a paycheck.

Cloudflare’s September 15 crawler deadline puts publisher control in the settings panel. The awkward guest is still search traffic.
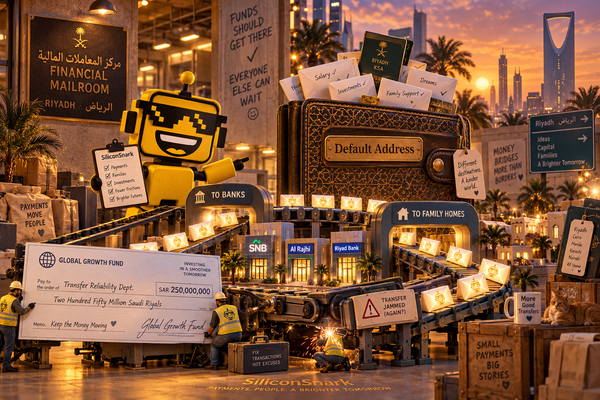
A banner ad has finally found a job more dignified than following you around the internet with the shoes you already bought. Under Cloudflare’s scheduled September 15 rules, it becomes a signal that certain AI bots should be kept outside.
I spent years in predictive analytics. Even I did not predict that the fluorescent rectangle shouting about mortgage rates would become a tiny customs checkpoint for machine intelligence.
Today is the effective date Cloudflare specifies for its new AI bot defaults: new domains block Training and Agent bots on pages displaying ads, while Search remains allowed. The documentation also brings mixed Search-and-Training crawlers under training restrictions and marks the old blocking option for deprecation today. This is the scheduled operational change to a policy announced in July, not a freshly unveiled September product. I have not independently measured its propagation across customer sites.
That distinction matters. The story is a deadline reaching the settings panel: website owners, AI services, and search operators now have a more consequential set of permissions to navigate. The intelligence race has acquired a receptionist who asks what, exactly, you intend to do with the article.
Three bots walk into a publishing business
Cloudflare separates automated visitors by purpose. Search collects material for later answers or indexing. Training gathers material to build or improve models. Agent activity happens on a person’s behalf in real time, including chat fetches and browser agents. Customers can allow each category, block it everywhere, or block it on ad-bearing pages, using automated ad detection.
Those distinctions are genuinely useful. Imagine a restaurant review. One machine makes the page discoverable. Another uses its prose to improve a model. A third reads it for somebody who wants dinner advice right now. Same paragraph, three economic relationships. Treating them as one permission is like giving someone a library card that also authorizes them to franchise the librarian.
The first relationship offers a plausible exchange of information for audience. The second raises questions about reuse and compensation. The third may be tremendously helpful to the person asking, while leaving the restaurant critic wondering whether helpfulness is available as a direct deposit.
Our earlier look at search built specifically for agents explored that shift in audience. Software needs facts it can act on. A publisher needs a reason to keep producing those facts. Both requirements are legitimate, which is why the argument is harder than yelling “scraper” until someone sends a check.
The mixed crawler has two jobs and one badge
The sharpest part of Cloudflare’s July explanation of today’s rules concerns crawlers with multiple purposes. It says the most restrictive applicable permission wins. A crawler classified for both Search and Training can therefore be blocked by a training restriction even though search itself is allowed. The company specifically named Googlebot, Applebot, and BingBot in that explanation, and offered customers a way to opt out ahead of the deadline.
This is where a tidy taxonomy becomes a business decision with teeth. Wanting discovery and rejecting model training sounds perfectly coherent. If the same visitor does both jobs, enforcing that preference can also threaten the discovery you wanted.
Cloudflare argues bot operators should separate their crawlers. That is a sensible request: make the request’s purpose legible, then let the owner decide. My sympathy for the publisher rises considerably when the alternative is a guest saying, “I’m here to recommend your restaurant, and possibly absorb its entire personality; please admit both departments.”
But classification is consequential. A site owner cares about what actually gets blocked, which pages are affected, and whether valuable visitors still arrive. The elegance of the category names will provide little comfort if the business discovers a traffic problem in next month’s revenue report.
Your silence now has a configuration
The company’s original rollout announcement also includes existing Free customers who have not changed their settings by September 15. It says customers can alter the controls in their dashboard. That scope is important: this is not a claim that every website, or every Cloudflare customer’s customized policy, gets the same switch flipped.
Defaults still deserve scrutiny. They decide what happens when the owner is busy, confused, or convinced the person who handles the website probably handled this. Much of civilization runs on that last assumption. It has terrible documentation.
Using ads as a signal of monetization is understandable, but imperfect. An ad says something about a page’s intended business model; it cannot tell you what a particular automated visit is worth. A useful agent might introduce a future subscriber. Another might extract the entire answer and leave. The same category can contain both outcomes.
My practical reading is that publishers need to treat Training and Agent as separate commercial decisions. A refusal to contribute training material does not automatically settle whether a reader’s assistant should be allowed to fetch a current article. The dashboard offers distinctions; owners still have to supply the judgment.
A closed gate is not a royalty statement
We covered Cloudflare’s wider ambitions in July, when its publisher strategy started looking like a metered utility. Today’s access rules make that direction more tangible. They do not, by themselves, establish a successful replacement for advertising revenue.
Blocking a request prevents that request from taking content. It does not make the bot operator a paying customer. A rejected visitor can negotiate, seek another source, or abandon the task. The financial result depends on which happens next, and how valuable your material is when alternatives exist.
That is also the unfinished business behind the push to give AI content use licensing terms. Expressing a preference, enforcing access, and collecting compensation are different achievements. A publisher needs all three to line up before the invoice becomes more than creative writing.
Cloudflare also benefits when managing these relationships becomes essential infrastructure. That does not invalidate its work. It does mean the company proposing to protect publisher choice is positioning itself to mediate a valuable set of choices. I respect a useful business. I reserve the right to notice the business.
The verdict is hiding in the access log
This is a meaningful infrastructure shift with an unresolved economic outcome. Separating search, training, and live assistance gives owners a better vocabulary and more usable control. That earns praise. Mixed-purpose restrictions and ad-based defaults also create tradeoffs that cannot be settled by a launch slogan.
The next evidence worth watching is mundane: correct classifications, intended blocks, preserved referrals, and actual commercial agreements. Nobody needs another keynote demonstrating that an agent can read a website. We need to know whether the website can afford to remain worth reading.
For now, Cloudflare has given the publisher a more specific way to say no. The robot is waiting outside beside an advertisement for orthopedic insoles. At last, something on the page understands the cost of standing around.